
Midoo AI
The world's first AI language learning intelligence provides users with a highly personalized, authentic and effective language learning experience through dynamically generated learning paths and immersive scenario dialogues.
An open-source AI-powered research and report generation agent that automatically retrieves information from the web and local sources, compiles research reports with citations, and supports self-deployment and integration with Python.
 GPT Researcher
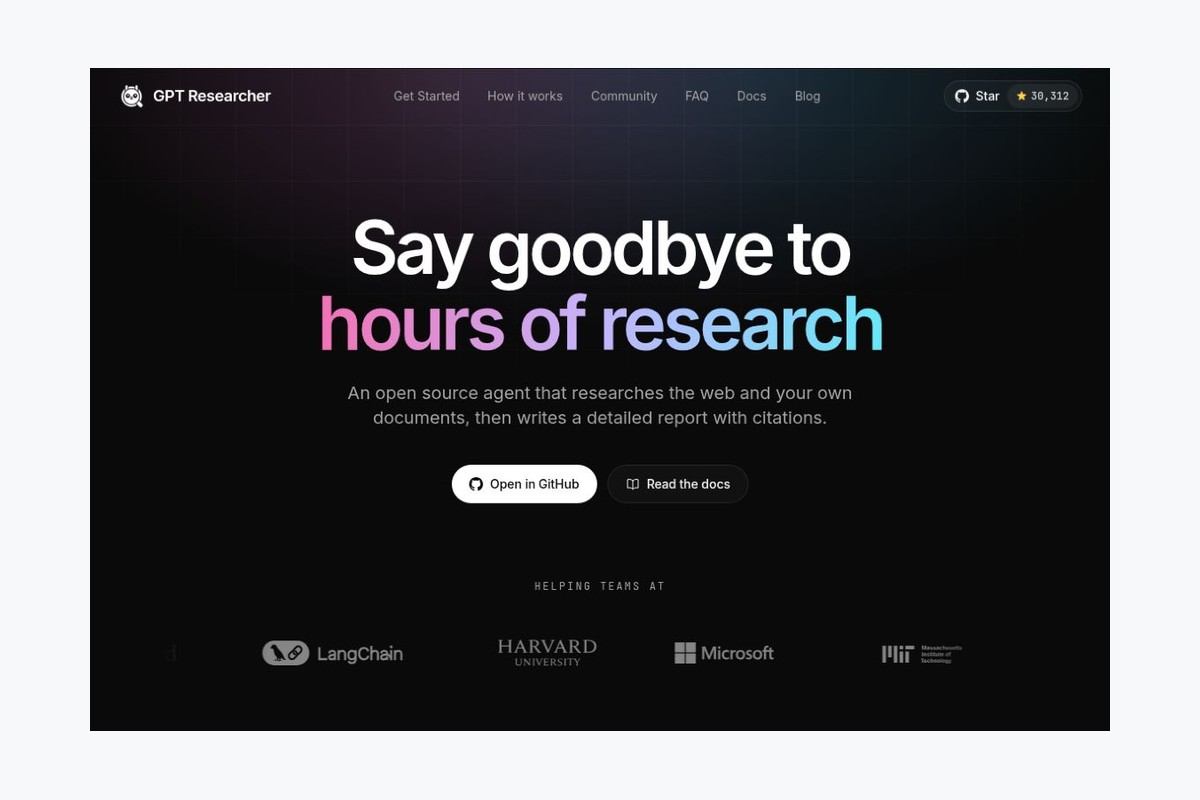
 is an open-source AI research agent initiated by Assaf Elovic and maintained by the community. It is not designed for simple Q&A, but rather to “gather information on a topic and then write a research report with sources”: it first breaks down the research task, then searches the web or local documents, organizes the information, and generates a lengthy output. For those who frequently conduct industry research, technical comparisons, and literature reviews, it functions more like a research infrastructure that can be integrated into their own workflows.
In the official introduction, the project’s founder explains that the design was intended to reduce the manual effort required to repeatedly search across multiple web pages and compile information. GPT Researcher provides source code, Python packages, and accompanying documentation, allowing developers to set up their own services or integrate the research capabilities into their applications. The repository is licensed under the Apache License 2.0; users must comply with the license terms and attribution requirements when using, modifying, or distributing the software. Please note that while the software is open source, this does not automatically grant the same license to third-party models, retrieval services, or brand materials.
Product teams can use it to organize the publicly available features and positioning of competing products; content creators can first establish a framework for their research materials and then verify key conclusions one by one; developers can embed special reports, vendor comparisons, or technology selection reports into internal tools. For general searches where users simply want an immediate answer, it may seem overly complex; however, it truly demonstrates its value for tasks that require a stable structure, verifiable sources, and follow-up processing.
Deploying code does not mean there are no costs: model calls, search APIs, servers, and storage may each incur separate charges, and as research becomes more in-depth, the number of calls and the time required typically increase. Cited links also do not guarantee the accuracy of conclusions; outdated web pages, biased sources, and model misinterpretations still require manual handling. When dealing with internal documents, you should first confirm the data flow and confidentiality requirements of the model and retrieval services; data collection must also comply with website access rules and copyright laws. Since the project positions itself as an experimental application, automatically generated reports should not be directly relied upon as a reliable basis for professional judgment or academic papers.
| sports event | Main Focus | Reasons Why It's a Good Choice |
|---|---|---|
| GPT Researcher | Search for, research, and generate reports on specific issues | We hope to standardize the literature review process and document the sources for future reference. |
| RAGFlow | Document Analysis, Knowledge Retrieval, and Agent Workflows | The focus is on building a knowledge base from existing data, rather than simply producing thematic reports. |
| LibreChat | Multi-Model Dialogue and Agent Interaction Portal | What’s more, we need a unified chat interface, with different tools and models integrated as needed. |
The strength of GPT Researcher lies in breaking down the process of “finding information—organizing evidence—drafting a report” into configurable workflows. It is suitable for researchers and development teams willing to handle deployment, cost management, and fact-checking; however, it is not the right tool for those expecting to deliver final conclusions without any configuration or review.
Official Source:Project website - GitHub Repositories - Getting Started Guide - Python Package Description - About the Founder - open source license


 简体中文 简体中文
 English