
Ingenieur AI
A global literature AI platform that integrates intelligent search, interpretation, management, analysis and cutting-edge tracking, utilizing advanced AI technology to improve the efficiency and quality of scientific research.
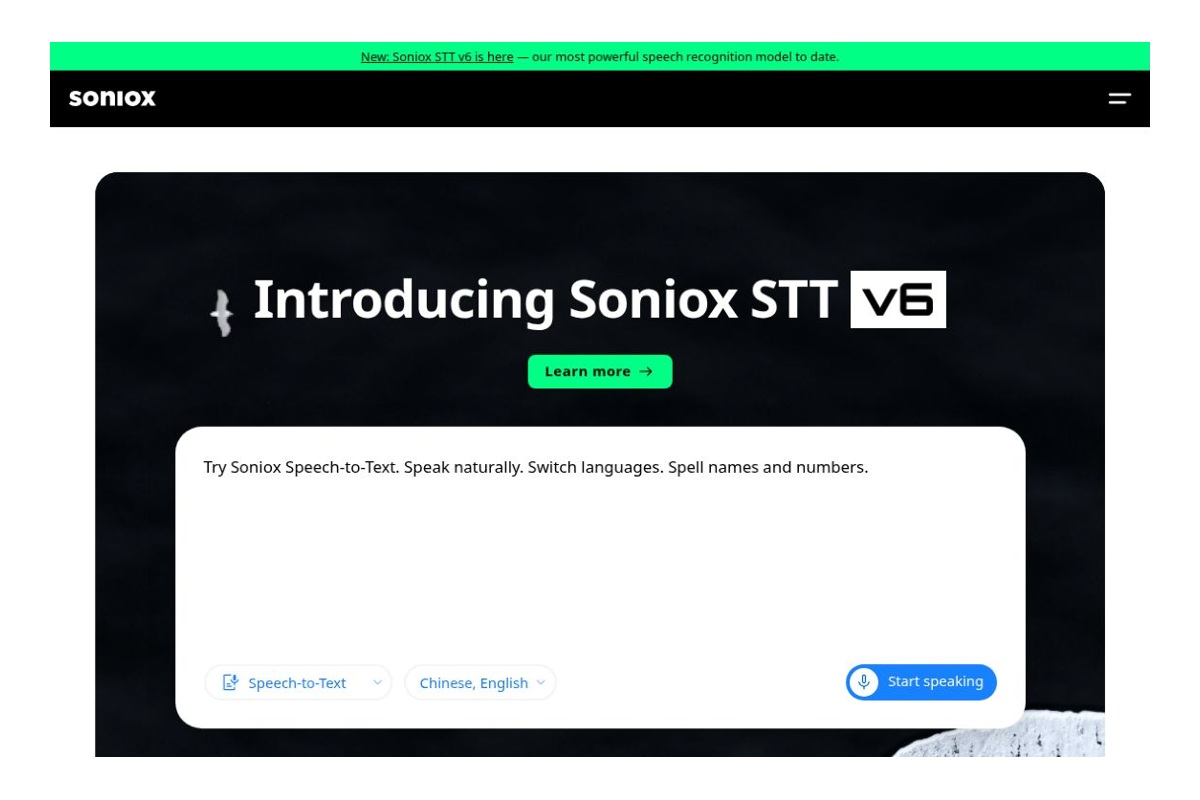
Soniox offers real-time and file-based transcription APIs. STT v6 introduces proxy text context and proxy speech echo cancellation, designed for voice assistants, conferences, and dictation; however, performance claims still require verification using actual business audio.
 Soniox
 offers real-time and file-based transcription APIs. STT v6 introduces proxy text context and proxy speech echo cancellation, designed for voice assistants, conferences, and dictation; however, performance claims still require verification using actual business audio.
Official Website Soniox
Soniox is a voice AI platform. Its official website distinguishes between the application portal and the developer API portal, offering speech recognition, translation, and text-to-speech services. This article focuses on its speech-to-text capabilities, which are ideal for development teams that need to convert real-time conversations or recordings into processable text.official website
STT v6, released on November 3, 2026, adds two capabilities for voice agents: passing text prepared for playback by the agent to the recognition model to help understand the user’s brief responses; and using this context to filter the audio played by the agent while continuing to recognize user interjections. According to the official documentation, v6 includes both real-time and asynchronous models and supports more than 60 languages. This represents the scope of the announced capabilities; terms such as “most accurate” and “significantly improved” remain vendor claims and should not be interpreted as guaranteeing the same results for all accents, devices, or industries.Release Notes
Real-time transcription is suitable for voice assistants and captioning systems, while asynchronous transcription is better suited for processing recordings of meetings, interviews, or customer service calls. Speaker tags, language recognition, and translation help with subsequent tasks such as generating meeting minutes or retrieving content; however, these tags do not serve as confirmation of the speaker’s identity, and an accurate transcription does not guarantee that downstream summaries will be accurate.Getting Started Guide
For voice product developers, what makes v6 noteworthy is its ability to understand “which stage of the conversation is currently underway.” For example, if an assistant has just listed two options and the user responds with only one of the names, the context may help reduce ambiguity. For teams developing meeting products, the focus should be on handling overlapping speech, speaker transitions, and proper nouns; for voice-input products, the emphasis should be on checking numbers, units, dates, and mixed Chinese-foreign language input, rather than simply evaluating a clean audio recording.
1. Access the Developer Console from the official website, configure API access in your project according to the official documentation, and store the secret key on the server or in a secure environment variable.
2. First, run the official Python or Node.js example. For live audio, select "Real-time" mode; for existing files, select "Asynchronous" mode. You can also start with a file URL that you have access to.
3. Organize product names, proper nouns, and technical terms into contextual groups; then, have the voice agent incorporate the text for announcement according to the v6 interface requirements to verify echo cancellation and interruption behavior.
4. Compare transcriptions, speaker annotations, latency, and costs using approved audio sources, paying particular attention to noise, weak network connections, and overlapping speech, before integrating the data into the production system.
| artifact | Positioning and Focus | Suitable for the task | Important Limitations |
|---|---|---|---|
| Soniox STT v6 | Multilingual Transcription, Context, and Proxy Echo Handling | Voice Assistant, Meetings, Dictation | The appropriate interface must be connected; performance should be evaluated based on the actual audio. |
| Deepgram | Flux focuses on dialogue turns; Nova-3 focuses on general recognition. | Real-time transcription, streaming, or batch transcription | Flux and Nova-3 differ in their languages and scope of functionality, so they cannot be used interchangeably. |
| AssemblyAI | Provides audio transcription services along with related capabilities such as speaker identification and vocabulary analysis | Audio Processing and Content Analysis Pipeline | An API key is required for integration; specific models and features must be confirmed separately. |
When making comparisons, ensure that each provider processes the same source material and records any omissions, incorrect terms, tagging errors, and wait times. Do not treat the number of languages as a direct measure of accuracy for each language, nor should you equate translation support with professional translation review.
The API is billed based on input audio, input text, and output text tokens. The official conversion rates are approximately $0.10 per hour for asynchronous requests and $0.12 per hour for real-time requests. This is not a fixed flat rate; costs may vary based on context, translation output, and actual usage, and API prices cannot be directly applied to application-level subscriptions.Pricing Page
The service is primarily provided through cloud APIs, the console, and official application interfaces. Access from mainland China, payment options, and the specific region where data is stored have not yet been confirmed; businesses should verify these details before purchasing. Recordings containing personal privacy information or trade secrets must first obtain the necessary authorization; content related to medical matters, legal issues, and payment amounts should be manually reviewed, and the transcription model should not be treated as the definitive source of facts.




 简体中文 简体中文
 English