
Mocha
AI-driven, full-stack, no-code platform that allows users to quickly generate and launch complete web applications using only natural language descriptions.
A "local-first" shared memory app launched by Tencent Hunyuan allows authorized AI tools to access conversation and coding context; it is currently still in preview.
 MemHub
 organizes user-authorized AI conversations and coding logs into a local memory and allows authorized AI tools to access the relevant context. For users who frequently switch between tools such as Cursor, Codex, and Claude Code, it offers a way to reduce the need to repeatedly specify preferences, project context, and past decisions. The current version is still in the preview stage and is best suited for early adopters who are willing to verify permissions, install packages, and configure models.Official Product Description
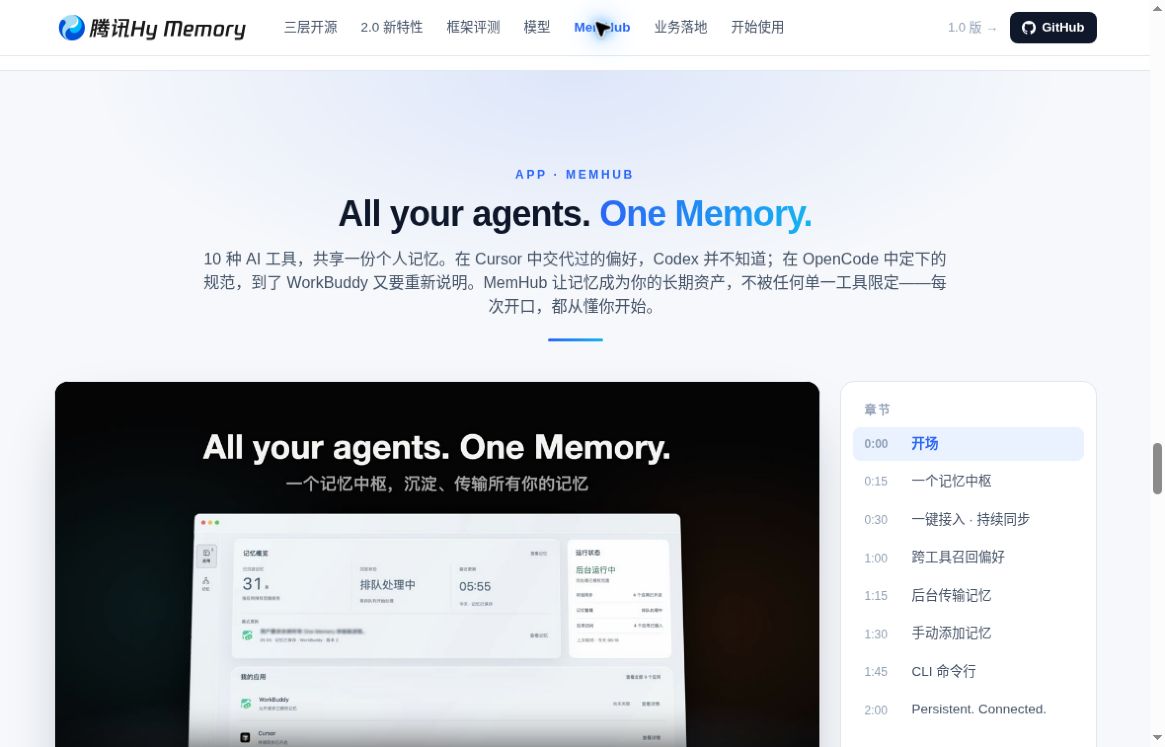
Figure:Tencent Hunyuan Official Website: MemHub Introduction SectionScreenshot (October 19, 2026). The image shows an official demo.
| sports event | Verification Results |
|---|---|
| name (of a thing) | MemHub |
| Team | Tencent Hunyuan; the code is available on the official Tencent-Hunyuan GitHub organization |
| Tool Type | A locally-priority AI shared memory application; provides a desktop interface and CLI |
| Initial Public Release | October 16, 2026 |
| Latest Verified Version | MemHub v1.0.4, released on October 18, 2026; npm CLI version 1.0.5 |
| Verified Products | macOS arm64 App/Runtime; Linux x64, arm64 Runtime |
| System Boundaries | The Mac app requires macOS 13 or later; Windows is not currently supported; no official versions for Intel Macs were found this time. |
| Code License | Apache License 2.0; third-party components are subject to their respective licenses. |
| Cost Assessment | No standalone pricing for MemHub is listed; models, vectorization interfaces, and computing resources may incur additional costs. |
| Official Portal | Products - MemHub Documentation - Release and Download |
Version and Platform Information v1.0.4 Release,Bill of Materials for This Versionup to Official npm Metadata.
During the launch of Hy-Memory 2.0, Tencent Hunyuan showcased three distinct layers: a model for memory read/write operations, a memory engine for developers, and the MemHub application for AI tool users. MemHub is the product responsible for connecting to and managing personal memories, while Hy-Memory provides the underlying memory capabilities. Installing MemHub is not the same as deploying a large model on your own.Official Release Page
From the user’s perspective, it can be understood as a memory bank with access boundaries: first, determine which sources can be read; second, decide which content is allowed to be fed into the model for processing; and finally, specify which tools can retrieve the memories. This adds an extra layer of ongoing management compared to simply copying a chat log to another assistant, but it also increases the number of configurations that need to be checked.
According to the official project history, Hy-Memory 1.0 was released in May 2026 and subsequently evolved into version 2.0, which includes chat, work, and coding scenarios. MemHub released its first set of products on October 16 and updated to v1.0.4 on October 18; the release notes included the addition of a diagnostic log export feature and bug fixes. It is an open-source project under Tencent’s Hunyuan initiative; currently, publicly available information is insufficient to support claims regarding independent startup teams, funding amounts, the number of paying customers, or user scale.Project History - Release Notes
MemHub can integrate with supported AI tools, incorporate past conversations into a unified memory, and continue processing subsequent sessions. Tools listed on the official website include WorkBuddy, Cursor, Codex, Claude Code, OpenCode, OpenClaw, Qwen Code, Pi, Hermes, and DeepSeek Harness. This list represents the officially announced scope of integration and does not imply that every host version or installation method has been verified by this site.List of Official Features and Tools
Architecture documentation retains the source text as local Evidence, which then undergoes memory processing, governance, and retrieval. The desktop client and CLI share the same runtime and data; they do not each create their own independent memory. Integration is achieved through Hooks, Skills, plugins, or MCP, with the specific method depending on the host tool.Architecture Documentation
The Memory Engine can distinguish between daily preferences, task processes, and code-related contexts. For users, its value lies in enabling new sessions to retrieve previous constraints and decisions; actual retrieval still depends on whether data has been successfully imported, whether the content has been consolidated into usable memory, whether authorization scopes match, and whether host integration is functioning properly. Do not equate “successful connection” directly with “correct recall every time thereafter.”Hy-Memory Scenario Description
Allowing MemHub to read a particular source does not automatically mean that all other tools are permitted to read its content. The architecture clearly distinguishes between source authorization, sync toggles, model content authorization, and host recall authorization. For workflows involving multiple clients or projects, you should verify each item individually during actual testing rather than granting access to all sources at once.Permission Boundaries
If you’re only performing short tasks within a single assistant, the existing project documentation or built-in memory may already be sufficient. If you require a solution that requires no configuration and reliably supports all operating systems, the current preview version should also be considered.
As of the verification date, the v1.0.4 manifest includes DMGs for Apple Silicon Macs, as well as macOS arm64 and Linux arm64/x64 runtimes. The minimum system version for Mac apps is macOS 13. Although some documentation mentions macOS x64 as a release target, the current manifest does not include packages for Intel Macs; therefore, it cannot be marked as supported based on this information. Windows is explicitly listed as unsupported in the project documentation.v1.0.4 Bill of Materials - Installation Documentation
Mac users can select the appropriate DMG file from the Release page. CLI users must first ensure they meet the Node.js 24 or higher requirement specified in the npm package. When downloading, verify the checksum information published by the official source; do not treat third-party reposted packages or builds lacking the corresponding manifest as officially supported artifacts.
The CLI procedure provided in the official installation documentation is as follows:
npm install -g memhub-cli
memhub install
memhub init
memhub status
The npm package is only a bootstrapper; the full runtime is downloaded during subsequent installation steps. If you encounter an error, you can use `memhub doctor` as described in the documentation to check the status. The Linux background service requires an active systemd user session.Installation process
The npm version detected during this verification is 1.0.5, and its published bootstrap code points to Runtime 1.0.4. The fact that the version numbers differ does not necessarily indicate an installation error.npm Package Metadata
We recommend first selecting a host and a small number of non-sensitive conversations to verify the scope of data read by the source, processed by the model, and read by the target tool. The runtime configuration includes LLM and embedding parameters; API keys should be managed through the product’s secure storage mechanism. Do not include keys in regular chats, message bodies, or public issue reports.Model Configuration Instructions
You can test this using a sample preference that does not contain sensitive information, such as “Start the project description with a three-line summary, followed by a list of items to be confirmed.” Open a new session in another approved tool to check whether it can find this content, while also reviewing the processing and permission statuses in MemHub. Then modify the preference and observe whether subsequent references still use the old content.
Closing the desktop window does not necessarily stop the background runtime. By default, the program retains its memory; there are separate commands and confirmation processes required to completely delete data. Before the trial period ends, you should check the actual status of the background service and local data according to the official documentation, rather than assuming that “the icon has disappeared” means “the data has been cleared.”Operations and Data Lifecycle
"Local-first" refers to the storage and execution architecture and should not be interpreted to mean that all processing takes place on the user’s computer. The official privacy statement specifies that when users select a third-party model, the data required to complete the task will be sent to that service. Therefore, for sensitive data, users should first verify the service provider, the scope of data transmission, and the intended use before deciding whether to import it.Privacy Statement
The official statement also clarifies that the product does not include the screen, OCR, keyboard and mouse, clipboard, or background audio recording. However, when debug mode is enabled, local debug logs may record the model’s inputs and outputs; switching back to the normal log level will not automatically erase existing debug files. You must still review and anonymize the data yourself when troubleshooting issues or submitting logs.Log Privacy Boundaries
It is recommended to evaluate personal preferences, publicly available project materials, and confidential client information separately. Information recalled from memory may influence subsequent responses and may no longer be current; when decisions involve payments, publication, editing, or important judgments, you should always refer back to the most recent original documents for confirmation.
The LICENSE file in the MemHub code explicitly states that it is licensed under the Apache License 2.0, and the NOTICE section includes a copyright notice from Tencent. Open-source code licensing and the billing and account terms for third-party model services are separate matters; one cannot infer from “open source” that “everything is free” or that “any materials may be freely reused.” When redistribution or commercial integration is involved, you should read the LICENSE, NOTICE, and third-party attribution documents together.authorization - NOTICE
In the official release pages and documentation reviewed for this article, no pricing table for standalone MemHub subscriptions was found. Actual usage costs depend on the selected LLM, embedding service, network conditions, disk usage, and maintenance time; while the official documentation provides configurable model endpoints, it does not specify a fixed monthly fee applicable to all users.Basis for Configuration
The table below compares product positioning and access methods; it should not be interpreted as a performance test based on the same dataset.
| programmatic | Main Forms and Uses | When making a selection, you should focus on | Cost Boundary |
|---|---|---|---|
| MemHub | Local applications and the CLI: Consolidate authorization sessions for supported tools and provide revocation | Current platform products, host compatibility, Type 3 authorization, and preview status | Licensed under the Apache 2.0 License; model and operating costs are billed separately. |
| Mem0 | SDK/API memory infrastructure that provides a hosted platform as well as open-source solutions for self-deployment | It is more appropriate to integrate memory into your own application; you need to clearly define the scope of isolation between the user and the agent. | The official platform offers both a free tier and paid plans; the "Starter" plan is listed at $19 per month. |
| Supermemory MCP | Host the MCP memory service, support MCP clients via OAuth connections, and grant permissions on a per-space basis | Prefer the use of managed services across clients; must accept the data and billing boundaries associated with those services | The official plan includes a free monthly allowance; the Pro plan costs $19 per month; usage is deducted from the allowance as it occurs. |
| Claude Code Built-in Memory | Project documentation and automatically recorded history, used in Claude Code sessions | 如果主要使用一个编码工具,可以先评估现有能力;不等同于独立多工具历史汇总应用 | 按 Claude Code 本身的使用方案核对,本文不额外推定价格 |
比较依据:Mem0 产品文档,Mem0 快速开始,Mem0 定价,Supermemory MCP,Supermemory 定价,Claude Code 记忆文档。价格为核验日页面所示,不能假设不同服务的额度和计费单位相同。
简单判断:想给已有多个工具建立个人记忆库,可先评估 MemHub;要为自建应用设计记忆接口,可优先研究 Mem0 或 Hy-Memory SDK;希望托管接入多个 MCP 客户端,可比较 Supermemory MCP;只需要固定项目规则,则先把现有说明文件整理好。
值得关注的是,MemHub 把“多个工具共用一份背景”做成了独立应用,并公开了来源、模型处理和读取授权的架构。它的价值是否成立,应以自己的工具组合和真实工作流验证。
目前应注意这些限制:
这些判断结合了 preview 声明,发布清单与前述权限、隐私文档。
目前不能标注为支持。官方文档明确写明 Windows 不支持。
MemHub 是该团队公布的独立共享记忆应用,属于 Hy-Memory 2.0 的应用层。它需要单独安装和配置,不能因为使用了混元或其他 AI 工具就推定已启用。
不要把模型、框架和应用混为一项安装要求。MemHub 内嵌记忆 SDK,并使用模型配置;官方应用流程并未要求每个用户都先在本机部署该 30B 模型。
不能保证。建议分别检查导入、记忆处理和目标工具召回,并用明确、可追溯的示例验证。重要结论仍需人工核对来源和时效性。
优先使用 Tencent-Hunyuan/Hy-Memory Releases 和有效的 MemHub 文档目录。核验时官网部分按钮指向的独立 MemHub 仓库返回 404,因此本文采用当前有效仓库,不把失效链接作为下载入口。
MemHub 适合把多个 AI 工具用于长期工作、又愿意管理本地环境和授权的人。建议先在受支持平台,用少量非敏感数据完成一次“导入、召回、纠正、撤权”的小范围验证,再决定是否扩大使用。它提供了一个值得观察的共享记忆入口,但当前资料不足以支持对稳定性、召回效果或长期成本作统一承诺。


 简体中文 简体中文
 English